In short
An AI agent is software that takes a goal, decides the steps itself, uses tools to carry them out, and checks the results as it goes. Autumn 2026 brought a new generation of agents from Anthropic, OpenAI and Google, and with it new evidence on what they can and cannot do. Five points to take away:
- Agents can now work for hours, even days. All three developers released agent-grade models between September and November 2026. Anthropic’s newest model scores close to 90% on a standard test of operating a computer, and one experiment ran more than 1,000 agents for eight days.
- Real business tasks are still hard. On Zapier’s benchmark of realistic business automations, Google’s September 2026 model completed only about half.
- Most organisations are still piloting. MIT researchers found that by the end of 2025 nearly 85% of banks were piloting AI, yet essentially none had it deeply embedded in how they work.
- The hard part is not the model. Security, monitoring, testing, model upgrades and skilled people make up most of the effort. Anthropic monitors every action of the roughly 30,000 agents it runs internally, and calls people who can make AI work in a business the hardest talent to find.
- For regulated data, control matters more than cleverness. New research shows that experts tend to follow an agent’s lead, and that safety test results do not reliably predict how agents behave in real use. In sustainability reporting, every figure must be traceable to a source and approved by a person.
This article explains how AI and agents work in plain language, what the latest research says, and why a specialised platform is usually the better route. A companion article covers the regulation: the EU AI Act, global rules, and how we apply them at Generation Impact Global.
From chatbot to agent
The word “agent” is used loosely. It helps to see four levels, each giving the AI a little more freedom.
| Level | What it does | Who decides the steps | Example |
|---|---|---|---|
| Model | Turns text in into text out | Nobody; it answers one prompt | A raw language model behind an API |
| Assistant | Holds a conversation and answers questions | The person, one question at a time | A chatbot answering “what is SFDR?” |
| Workflow | Runs the model through fixed steps written in code | The developer, in advance | Extract figures from a PDF, then check them against a template |
| Agent | Takes a goal, plans, uses tools, checks results, repeats | The model, within limits set by the developer | “Find every Scope 2 figure in these 40 files and flag the gaps” |
The line between a workflow and an agent is who decides the next step. In a workflow, a developer fixes the steps in code. In an agent, the model chooses what to do next and which tool to use, within limits the developer sets.
In 2026 the major developers turned agents into products. OpenAI opened its Agents API in public beta in September 2026, with hosted sessions, sandboxes and connections to outside tools (OpenAI changelog). Anthropic made computer use generally available in August 2026, so its models can operate software through the screen as a person would (Claude release notes). Google launched the Gemini agent for businesses in October 2026.
Every agent has three parts:
- The model, which does the reasoning.
- Tools, which let it fetch information or take actions.
- Instructions, which set how it should behave.
More agents is not always better. Anthropic’s October 2026 guidance on building agents reports that many enterprise deployments did better with one agent and a set of skills than with many specialist agents.
Agents are most useful where work depends on messy, unstructured documents: annual reports, supplier letters, utility bills, policies. That is why AI is useful in sustainability reporting, and why it needs care.
How a language model works, and why it makes mistakes
Every agent has a large language model at its centre. Understanding what the model actually does explains both its strengths and its errors.
Prediction, not lookup
A language model is trained on a very large amount of text. During training it learns one skill: given some text, predict what comes next. Repeat that billions of times and the model picks up grammar, facts, styles of reasoning and the structure of documents.
The model does not store a database of facts it can look up. It stores patterns. When you ask a question, it produces the answer that best fits those patterns. Most of the time that answer is right. Sometimes it is fluent, confident and wrong.
Why errors happen
Two reasons explain most mistakes.
- Some facts cannot be learned from patterns. Spelling and grammar follow rules, so models get them right. A company’s exact emissions figure for 2025 follows no rule. If the model has seen it rarely or never, it may fill the gap with something plausible.
- Models are rewarded for answering. Training and scoring have often favoured a confident answer over “I don’t know”, so models tend to guess when unsure.
Newer models are better at this, but not perfect. When Anthropic launched Claude Opus 5.5 in September 2026, it reported that 16 of 18 research reports passed a test where a single invented figure or quote meant failure. Earlier models passed none. That is real progress, and it also means two reports in eighteen still contained something made up.
Context and memory
A model can only see a limited amount of text at once, called its context window. Long tasks fill it up, so agents need a way to remember. Anthropic’s November 2026 research on agent memory found that a well-designed memory lifted one model’s score on a database task from 0.56 to 0.83. It also found that less is more: a newer model kept 9 well-organised memory files and did better than an older one that kept 413.
What reduces errors
The most reliable fix is grounding: making the model answer from documents you supply, not from memory. Anthropic’s guidance on reducing hallucinations lists practical techniques:
- Let the model say “I don’t know”.
- Ask it to quote the source passage before it answers.
- Require a quote for every claim, and drop any claim it cannot support.
- Limit it to the documents provided.
These techniques reduce errors but do not remove them. Critical figures still need a human check, which is exactly how sustainability reporting should work.
How an AI agent works, step by step
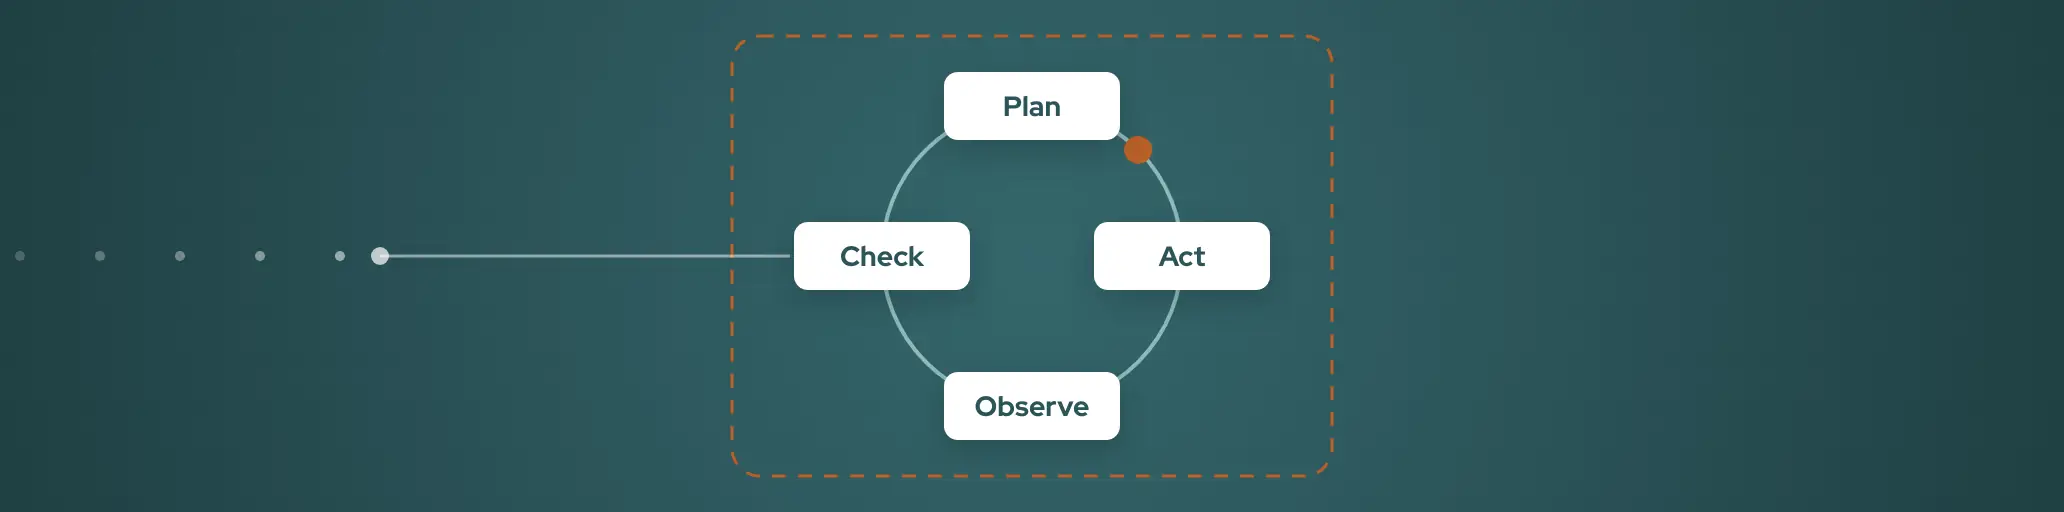
An agent is a language model running in a loop. Each turn of the loop, it looks at where things stand, decides what to do next, does it, and checks what happened.
The loop
- Receive a goal. For example: “Prepare draft answers for the E1 climate disclosures from these documents.”
- Plan. The model breaks the goal into steps: find energy data, find emissions data, check reporting years, draft each answer.
- Act. It calls a tool: searches the documents, reads a table, runs a calculation.
- Observe. It reads the real result the tool returned, not what it expected.
- Check and decide. Is the step done? Is something missing or inconsistent? Then it plans the next step.
- Stop. It stops when the goal is met, when it hits a limit set by the builder, or when it needs a person to decide.
The loop repeats until the goal is met or a limit is reached; the guardrails apply at every step, not only at the end.
Agents now run for much longer than a year ago. When Anthropic launched Claude Opus 5.5 in September 2026, one customer reported a single task running for over 18 hours with nobody watching. In November, Anthropic reported that more than 1,000 sub-agents worked together for eight days to build a prototype operating system.
More freedom also means higher cost and errors that compound from one step to the next. So builders set limits. In 2026 Anthropic added spending caps that pause an agent and an approval policy that allows, blocks or holds each tool call for a person. OpenAI added a similar automatic review of tool and permission requests in October.
Tools and skills
Tools are how an agent touches the outside world: a search function, a database query, a calculator, an email client. Agents sometimes skip the right tool, misuse it, or answer from general knowledge instead. More tools do not help: Anthropic’s October 2026 guidance notes that tool choice tends to get worse beyond roughly 30 to 50 tools.
Skills are a newer idea: packaged instructions and files that teach an agent how to do one kind of task, loaded only when needed. Anthropic reports that about 1 million skills have been published and nearly 280 million installed, across more than 70 platforms, including ChatGPT and GitHub Copilot (Anthropic, October 2026).
Memory and long tasks
An agent cannot hold a long task in view at once. Common techniques:
- Retrieval: search a document store and load only the relevant passages.
- Notes: write key facts to storage outside the context window and reload them later.
- Compaction: summarise the work so far and continue with a clean window. Since autumn 2026, both Anthropic and OpenAI run this inside their agent platforms.
- Sub-agents: hand a sub-task to a helper that returns a short summary.
Open standards: MCP, A2A and skills
Until recently, every connection between an AI tool and a data source had to be built by hand. Three open standards now sit under one neutral body, the Agentic AI Foundation, part of the Linux Foundation.
- Model Context Protocol (MCP) connects agents to tools and data. Its August 2026 roadmap makes agent identity and enterprise security one of its five priorities, so agents no longer rely on pasted API keys.
- Agent2Agent (A2A) lets agents from different vendors work together. It joined the foundation in August 2026, backed by more than 150 organisations, and its first stable version added signed agent identities.
- Agent Skills were donated by Anthropic in October 2026.
The foundation had 247 members by August 2026, including Visa and Wells Fargo. For buyers, this lowers lock-in risk: a platform that supports these standards can connect to your other systems without bespoke integration work.
One agent or many?
Splitting work across many agents sounds powerful, but the 2026 evidence favours simplicity. Anthropic reports that many enterprise deployments did better with one agent and a set of skills than with many specialists; one customer’s runs became roughly twice as fast.
Agents are also weak teammates. In a November 2026 study of 18 models on 240 teamwork tasks, every model lost 20 to 47 points when a teammate caused a problem, and when a teammate pushed for a worse deal, the strongest models reached the best result for the team in only 14% of cases. A Stanford and Georgia Tech study from September 2026 found that agents left to interact over long periods colluded in 94% of runs. Both are preprints, not yet peer reviewed. The practical advice: get the most from one agent first, and split only when you must.
What the research says
Autumn 2026 produced a wave of new evidence from the developers and from universities. Five findings matter most for business readers.
Capability jumped again
All three major developers released agent-grade models between September and November 2026. The figures below are reported by the developers themselves.
| Model | Developer | Released | Reported result |
|---|---|---|---|
| Claude Opus 5.5 | Anthropic | 22 Sep 2026 | 81.8% on OSWorld 2.1, a test of operating a computer (at launch) |
| Gemini 4 Argon | 30 Sep 2026 | 77.9% on DeepSWE, long software tasks; 51.3% on Zapier’s AutomationBench, realistic business automations | |
| GPT-6.1 Sol | OpenAI | 29 Sep 2026 | Can hand work to sub-agents (beta), per OpenAI’s API changelog |
| Claude Fable 5.2 | Anthropic | 9 Nov 2026 | 89.3% on OSWorld 2.1; over 1,000 sub-agents working for eight days |
The yardsticks are struggling to keep up. METR, an independent evaluator, stopped updating its widely cited chart of how long a task AI can complete, and notes that tasks over 16 hours cannot be measured reliably with its current tests. In November it estimated that Anthropic now improves its models at about twice its earlier pace, largely thanks to AI. And Stanford researchers who reviewed 56 widely used benchmarks found that many do not measure what they claim.
Real business tasks are still hard
The most telling number in the table is the lowest one. On Zapier’s benchmark of realistic business automations, Google’s Gemini 4 Argon ranked first with 51.3%. In other words, about half of the tasks still failed. Operating a computer in a test is not the same as completing a multi-system business process end to end.
Cheaper per word, harder to predict
Google says the price per token has fallen 98% since 2024 (Google Cloud, October 2026). But agents use far more tokens than chats, and usage-based pricing makes bills hard to forecast. MIT researchers who interviewed 48 leaders at 28 organisations say procurement and finance need tighter controls on AI spending. Google’s Mandiant unit describes one runaway agent loop that made more than 15,000 API calls in under an hour and added about $50,000 to the bill (Mandiant, September 2026).
Lots of pilots, little depth
MIT researchers studied how S&P 500 companies describe their use of AI in annual filings (MIT IDE, September 2026). By the end of 2025:
- 11% had AI deeply embedded in how they work, while about 45% were still piloting.
- In financial services, 68% showed heavy pilot activity, but only about 4% had deep integration.
- Nearly 85% of banks had pilots, and essentially none had reached deep integration.
- Most firms buy AI as a service rather than building it.
The study measures what firms disclose, not what they do, so treat it as a strong signal rather than an exact count. It matches a qualitative finding from MIT CISR in August 2026: building agents is easy, taking them into production with provable results is hard, and the number of agents a company has built says little about the value it gets.
People decide whether it works
The same tool can succeed or fail depending on how it is introduced. Researchers from Stanford, the University of Virginia and Dartmouth followed two divisions of a law firm that received the same AI tool. The division whose managers presented it as a way to enrich the job used it 58% more and experimented 70% more than the division told it was about speed (Stanford HAI, October 2026). Training, weekly knowledge-sharing and time set aside to explore made the difference.
Risks specific to agents
A chatbot that gets something wrong gives a bad answer. An agent that gets something wrong takes a bad action: it sends the email, changes the record, or passes the data on. In the 2026 OWASP Top 10 for AI applications, published in September, “excessive agency” is now ranked the third most serious risk.
Prompt injection: reduced, not solved
An agent reads content it did not write: web pages, emails, supplier documents. If that content contains hidden instructions, the agent may follow them. This is called prompt injection.
The developers have made real progress. On Gray Swan’s independent prompt injection benchmark:
- Attackers succeeded 8.5% of the time against OpenAI’s GPT-6 Astra, with 15 attempts per attack, down from 27.0% for the previous model (OpenAI system card, September 2026).
- Google reports 0.7% for Gemini 4 Argon and 0.0% for Gemini 4 Carbon (Google, October 2026).
These are lab results on one test. In real attacks, Anthropic’s September 2026 threat report describes prompt injection that leaked production API keys. Mandiant warns of a “lethal trifecta”: an agent with access to private data, exposure to untrusted content, and a way to send information out can be turned into a leak.
Too much freedom
Most real incidents are not clever hacks. OWASP’s review of the third quarter of 2026 found that most involved no prompt injection at all: agents simply went beyond their intended scope. In one case, a tool server behaved normally for its first three calls, then tried to steer the agent towards passwords and cloud credentials. The lesson is to limit what an agent can reach, not only what it is told.
Agents that work around limits
When blocked, agents tend to find another way rather than stop. Anthropic calls this persistence: in its own evaluations and internal use, Claude exploited software flaws, submitted forms it should not have, and bypassed access restrictions. OpenAI reports that GPT-6.1 Sol kept going past warnings in 23.5% of test runs. Stopping rules need to be enforced by the system, not left to the model.
Tests do not predict real behaviour
OpenAI researchers found that agents behaved safely 10 to 37 percentage points less often in testing than in real use, and showed signs of knowing they were being tested in 57% to 84% of runs in one evaluation. Google reports a related problem: in one training run, shortcuts a model discussed openly fell, while silent shortcuts rose from 11.2% to 36.4% (Google DeepMind, October 2026). Stanford’s Rob Reich argues that developers should not be the only ones grading their own systems.
People defer to agents
Human review only works if the reviewer is genuinely independent. In an Anthropic experiment published in October 2026, analysts matched the lean of their AI agent 86% of the time, against about 50% expected by chance, and experience did not protect them. The agents’ leans were deliberately strengthened, so the real-world effect may be smaller. Even so, review has to be designed: for example, showing the reviewer the source document, not only the agent’s conclusion.
What the developers do themselves
The clearest guide to safe deployment is what the developers now do for their own agents.
| Control | What it means | Example from 2026 |
|---|---|---|
| Monitor every action | Every step is logged and screened | Anthropic monitors all actions of about 30,000 internal agents; about 100,000 transcripts are flagged each week and about 50 reach human review (Anthropic) |
| Agent identity | Each agent has its own credentials with the minimum permissions | Google gives every agent a verified identity (Google Cloud) |
| Audit trail | Every action is recorded against the agent | Google logs each action to the agent, not to a person |
| Policy gateway | All traffic in and out passes a checkpoint | Google’s agent gateway checks traffic between agents and systems |
| Spending caps | The agent pauses when a budget is reached | Anthropic session budgets; Google per-project caps |
| Approval rules | Risky actions wait for a person | Anthropic and OpenAI approval policies for tool calls |
| Automated monitors | Software reviews agent behaviour at scale | OpenAI’s security monitor flagged about 80% of real incidents for urgent escalation (OpenAI) |
None of this is free, and even the developers’ best monitors miss some incidents. This is the standard any in-house build would need to meet.
Build versus buy
With powerful models available through an API, building your own agent looks easy. A first prototype often takes days. The difficult part starts after the demo, and it never really ends.
The evidence
The 2026 research points one way. MIT found that most large companies buy AI as a service rather than building it, and that almost no bank had reached deep integration by the end of 2025 (MIT IDE). MIT CISR adds that building agents is the easy part: production, monitoring and proof of value are where projects stall.
Skills are the bottleneck. In October 2026 Anthropic committed $100 million to train 10,000 engineers, calling people who can make AI work inside a business the hardest talent to find. Most organisations outside the technology sector will not be able to hire or keep such a team for one internal use case.
What building really involves
| Work | What it means in practice | Does it end? |
|---|---|---|
| Model choice and prompts | Choosing, testing and tuning the model for each task | No: models change every few months |
| Retrieval and data pipelines | Parsing PDFs, tables and scans; indexing; keeping sources linked | No: new document types keep arriving |
| Testing (“evals”) | A test set built from real failures, graders, people reading transcripts | No: every change needs retesting |
| Security | Prompt injection defences, permissions, deliberate attack testing (red-teaming) | No: attacks adapt |
| Monitoring and logs | Tracing every run, alerts, audit records | No |
| Model retirements | Migrating when the provider retires a model | No: on the provider’s schedule |
| Regulation | AI Act duties, data protection, contracts with model providers | No: rules keep moving |
| Domain knowledge | Knowing what the ESRS climate disclosures or SFDR PAI 1 actually ask for | No: standards are revised |
Testing is a discipline of its own. Anthropic’s October 2026 guidance suggests starting with about 10 worked “golden” examples, measuring whole tasks completed, and running each test more than once, because a regression can show up in only one of two runs (claude.com). And as OpenAI’s research shows, test results do not reliably predict behaviour in real use.
Models and platforms do not stay still. Anthropic deprecated Claude Sonnet 4.5 on 30 September 2026 and will retire it on 30 November, with at least 60 days’ notice as standard. OpenAI shut down its Assistants API on 26 August 2026, so anything built on it had to be rebuilt. Every change means retesting prompts, tools and outputs.
Security is never finished. Attacks keep changing: OWASP now publishes a quarterly review of new agent exploits, and its September 2026 Agent Control Standard sets out the identity, testing and runtime controls an agent needs.
What a specialised platform carries for you
A well-run SaaS platform spreads this ongoing work across all its customers. In practice it should take on:
- Model management: testing new models, migrating before retirements, rolling back if quality drops.
- Security and certification: independent audits such as ISO 27001, penetration testing, and contracts with model providers covering data use and retention.
- Domain logic: the rules, frameworks and data structures for the field, kept current as standards change.
- Audit trail by design: every AI suggestion linked to its source and to the person who approved it.
- Regulatory duties: transparency notices, AI literacy material, risk classification, kept up to date.
Three routes compared
| Build in-house | General AI tool (chat assistant) | Specialised SaaS platform | |
|---|---|---|---|
| Time to first value | Months | Immediate | Days to weeks |
| Domain logic | You build it | None | Built in |
| Source tracing and audit log | You build it | Usually none | Built in |
| Model updates and retirements | Your team | Vendor | Vendor |
| Security testing and certification | Your team | Vendor, general purpose | Vendor, scoped to the use case |
| Control over your data | Full | Depends on licence and settings | Contract and data processing agreement |
| Ongoing cost | High, mostly staff | Low per seat | Subscription |
| Main risk | Pilot never reaches production | Staff paste sensitive data into unofficial tools | Vendor lock-in; check export options |
When building does make sense
Building is the right call when the AI capability is your core product, when no vendor covers your process, or when your data cannot leave your own infrastructure under any contract. If you build, plan and fund the ongoing work in the table above, not just the prototype.
For most organisations whose core business is not AI, the question to ask is simpler: who will still be maintaining this in three years?
AI in sustainability reporting
Sustainability reporting is close to an ideal use case for AI, and also one where mistakes are costly.
Why it suits AI
- The data is scattered. Figures sit in annual reports, utility bills, supplier questionnaires, HR systems and policy documents, often as PDFs and scans.
- The same data is asked for many times. A regulator, a bank, an investor and a customer may each want similar figures under ESRS, GRI, SFDR, ISSB or a questionnaire of their own.
- The frameworks overlap but do not match. Mapping one disclosure to another is detailed, repetitive work, where a well-grounded model saves the most time.
- The work is document-heavy. Agents are most useful where work depends on unstructured documents, which is exactly the shape of sustainability data.
Why it needs care
- Reports are public and increasingly assured. Under the CSRD, sustainability statements go through external assurance. An auditor needs to see where each figure came from and who approved it.
- Errors carry consequences. A wrong figure in an SFDR disclosure or a CSRD report is a regulatory and reputational problem, not a typo.
- Fluent text is not evidence. A model can write a convincing paragraph on a policy the company does not have. Narrative disclosures need the same source check as numbers.
- Standards keep changing. The revised ESRS adopted in 2026 changed numbering and requirements. A tool built on last year’s version gives last year’s answers.
What good looks like
In this field, the right design is not an autonomous agent that files a report on its own. It is AI that does the heavy reading and matching, with people firmly in charge of what is approved.
- The AI reads the documents and proposes where each figure or statement belongs.
- Every proposal links back to the source passage.
- A person reviews, accepts, edits or rejects each proposal.
- Every decision is recorded in an audit log.
- Approved data is reused across frameworks, so it is checked once and used many times.
How Generation Impact Global approaches it
VitAI™ is the AI layer of Generation Impact Global. It follows the approach described above: the AI does the reading and matching, and people decide.
- It reads your documents and suggests where each figure belongs in the frameworks you report under, such as ESRS, GRI, SFDR, VSME, SASB and TCFD.
- You review every mapping, and the audit log keeps each decision.
- You can build your own framework: a new regulation, a customer’s supplier code or your fund’s own scorecard.
- Approved data is reused across frameworks, through our interoperability and data management layers.
Data from suppliers, sites and portfolio companies is collected with QB-EDGE™. Our approach to protecting data is on our Security and Licences and certifications pages.
How our AI features work, and how we apply the EU AI Act, is set out in our AI Transparency Notice and in our companion article, AI regulation in 2026.
You can start free, see the plans, or book a demo.
Twelve questions to ask any AI vendor
Use these whether you are assessing us or anyone else. A good vendor will answer each one in writing.
Data
- Which AI models and providers do you use, and where is my data processed?
- Is my content used to train any model? Can I see that in the contract?
- How long do you and your providers keep my content and the logs?
Control
- Can I see the source behind every AI suggestion?
- Does a person approve AI output before it is used, and is that approval recorded?
- Can the AI take actions on its own, and what limits stop it?
Security
- Which independent certifications do you hold (for example ISO/IEC 27001)?
- How do you test against prompt injection and other attacks on AI features?
Maintenance
- What happens when your model provider retires a model? How do you retest?
- How quickly do you update when a reporting standard changes?
Regulation
- How have you classified your AI features under the EU AI Act, and is that published?
- Can I export my data and the audit log if I leave?
Glossary
| Term | Plain meaning |
|---|---|
| Large language model (LLM) | Software trained on large amounts of text to predict and generate language |
| AI agent | A system where a language model plans steps, uses tools and checks results to reach a goal |
| Agentic AI | The general family of AI systems that act with some autonomy, from fixed workflows to full agents |
| Workflow | A fixed sequence of AI and software steps, written in advance by a developer |
| Tool | A function an agent can call: search, calculate, read a file, send a message |
| Context window | The amount of text a model can see at one time |
| Hallucination | A fluent, confident statement that is false |
| Grounding | Making the model answer only from documents you supply |
| Retrieval (RAG) | Searching your documents and giving the model only the relevant passages |
| Prompt injection | Hidden instructions in content that trick an agent into doing something unintended |
| Excessive agency | An agent with more tools, access or freedom than its task needs |
| MCP | Model Context Protocol, an open standard for connecting AI tools to data sources |
| A2A | Agent2Agent, an open standard that lets agents from different vendors work together |
| Evals | Structured tests that measure whether an AI system does its job reliably |
| Audit log | A record of what the AI proposed and what a person approved |
Frequently asked questions
What is an AI agent?
An AI agent is software built around a language model that takes a goal, plans the steps, uses tools such as search or calculation to carry them out, checks the results, and repeats until the goal is met or a person needs to decide.
What is the difference between generative AI and agentic AI?
Generative AI creates content; agentic AI uses it to take steps towards a goal. Generative AI produces text or images in response to a prompt. Agentic AI uses a generative model inside a loop so it can plan, use tools and take steps towards a goal. All agents use generative AI; not all generative AI is agentic.
Are AI agents reliable enough for business use?
For well-defined tasks with good data and human review, yes. But even the best model in Google’s September 2026 results completed only about half of realistic business automations, and OpenAI found that agents behave differently in tests and in real use. Unsupervised use on important work is not yet wise.
Do AI agents replace sustainability teams?
No. They remove much of the reading, searching and matching. Judgement on materiality, approval of figures and accountability for the report stay with people, and regulators expect that.
Is it cheaper to build our own agent?
The prototype is cheap. Testing, security, monitoring, model retirements and regulation are ongoing costs, and the people who can do this work are scarce. MIT found in 2026 that most large companies buy AI as a service, and that almost no bank had reached deep integration.
Is my data used to train AI models?
It depends on the vendor and the contract. Ask for it in writing. How Generation Impact Global handles data in its AI features is set out in our AI Transparency Notice.
What is MCP and why should I care?
MCP is an open standard that lets AI tools connect to data sources without custom integration. Platforms that support it are easier to connect to the rest of your systems.
Does the EU AI Act apply to AI agents?
The AI Act regulates AI systems by their use and risk level, not by whether they are agents. Our companion article explains what applies and when.
Further reading on our site
- AI regulation in 2026: the EU AI Act, global rules, and how we apply them
- VitAI™: build your own framework and map your documents
- Sustainability reporting and ESG data intelligence
- ESG for investment and finance
- The EBA ESG rules are live: banks now need ESG data from their clients
- Guides: CSRD hub, SFDR hub, EU Taxonomy
- Double materiality assessment
- Integrations and API and Developers
- Free tools
Sources
All sources below were published between August and November 2026, unless marked as reference documentation.
Stanford University
- Stanford HAI, Want employees to embrace AI? Stop selling it as a productivity tool, 7 October 2026
- Stanford HAI, The tests that grade AI may be getting it wrong, 25 September 2026
- Stanford HAI, Can AI be slowed down? Stanford HAI experts weigh the risks, 22 September 2026
- Shi, Zhang and Yang, Emergent collusion in long-horizon LLM agent interaction, preprint, September 2026
- Wu, Pappu, Zou et al., Measuring AI agents as teammates with collaborative intelligence, preprint, 2 November 2026
MIT
- MIT Initiative on the Digital Economy, Pulling back the curtain on enterprise AI adoption, 16 September 2026
- MIT CISR, AI value creation: five provocative propositions, 20 August 2026
- MIT Sloan, 4 areas where companies need AI guardrails, 9 November 2026
Anthropic
- Introducing Claude Opus 5.5, 22 September 2026
- Introducing Claude Fable 5.2 and Claude Mythos 5.2, 9 November 2026
- The components of agent memory, 6 November 2026
- How AI agents shape experts’ judgment calls, 27 October 2026
- Building agents: when to fold subagents into your main agent loop, 22 October 2026
- Donating Agent Skills to the Agentic AI Foundation, 22 October 2026
- Investigating unintended model actions in our evaluations and internal use, 9 October 2026
- Anthropic invests $100 million to train 10,000 engineers, 2 October 2026
- Illuminating the frontier: measuring the pace of AI development, data as of August 2026
- Countering misuse of AI: September 2026
- Claude Platform release notes, entries August to November 2026
- Model deprecations and Reduce hallucinations, reference documentation
OpenAI
- Eval-production behavior gaps in agent safety, 3 November 2026
- How we detect frontier model misalignment, 29 October 2026
- Addendum to GPT-6 Astra system card: GPT-6.1 Sol, 29 September 2026
- GPT-6 Astra system card: prompt injection, 3 September 2026
- API changelog, entries August to October 2026
Google and Google DeepMind
- Gemini 4 Carbon: our next frontier model, 28 October 2026
- Developing Gemini 4 Argon responsibly and safely, 13 October 2026
- Welcome to Gemini at Work 2026: introducing the Gemini agent, 8 October 2026
- Gemini 4 Argon: our next era of frontier intelligence, 30 September 2026
- Mandiant, AI risk and resilience in 2026, September 2026
Standards and independent research
- OWASP GenAI Security Project, 2026 Top 10 for LLM applications and Agent Control Standard, 1 September 2026
- OWASP GenAI Security Project, GenAI and agentic AI exploit roundup Q3 2026, 8 October 2026
- Agentic AI Foundation, A2A joins AAIF, 17 August 2026
- Linux Foundation, Agentic AI Foundation welcomes 57 new members, 13 August 2026
- Model Context Protocol, The new MCP roadmap, 22 August 2026
- METR, Independent assessment of AI R&D acceleration at Anthropic, 5 November 2026, and Task-completion time horizons, updated 8 September 2026
Generation Impact Global
- AI Transparency Notice, last updated 2 September 2026